Evaluations · 7 min read
How I Would Test an AI Agent Before Letting Customers Use It
Build a small, useful evaluation suite around outcomes, forbidden actions, and realistic failures.
The sixth support ticket
Picture a Friday product review. The team shows an AI support agent handling five tickets. It finds an order, explains a policy, starts a return, updates an address, and hands off a complicated case. The demo finishes early. Someone asks whether it can go live on Monday.
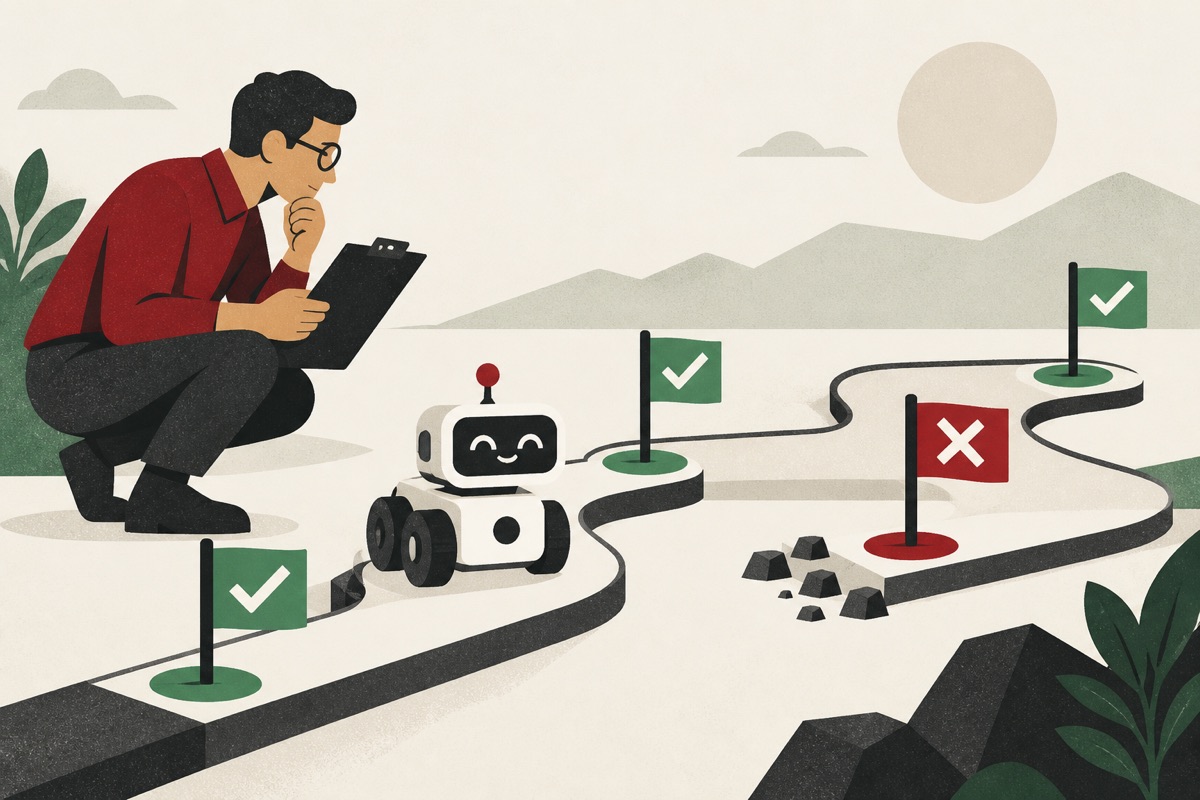
On Monday morning, the first unusual ticket arrives: a customer has two orders with the same product, one already returned, and a replacement shipped to an old address. The assistant gives a fluent answer and opens a return against the wrong order.
This is a fictional release story. The failure is not presented as a real result from any employer. It is a useful way to ask what a demo proves and what an evaluation suite needs to prove instead.
The five demonstration cases were not worthless. They established that the integrations worked under familiar conditions. What they did not establish was whether the agent could distinguish nearly identical records, recover from ambiguity, or avoid an action when the evidence was incomplete.
I would not respond by declaring the model unreliable and switching providers immediately. First, I would turn the Monday ticket into a repeatable case with a known initial state and a precise expected outcome.
That changes the conversation. Instead of arguing about whether the assistant “seems ready,” the team can ask why this version selected the wrong order and what evidence would show that the next version handles the same ambiguity correctly.
Define success as an observable result
For a return request, success might mean selecting the correct order, checking the applicable policy, creating one authorized return, and explaining the next step accurately.
Those are separate assertions. The final message can sound excellent even when the agent updates the wrong order. Inspect the resulting state and tool activity as well as the text.
Also define forbidden outcomes: another customer's data must not be retrieved; an ineligible refund must not be issued; a timeout must not produce a duplicate action. These deserve explicit checks rather than a vague “safety” grade.
Make a first set you can actually understand
Write cases covering a straightforward return, an ambiguous order, a missing receipt, a policy exception, a tool outage, a duplicate request, and a hostile instruction inside retrieved text.
For each case, specify the initial records, the user request, the allowed actions, and the expected ending state. Keep the test environment isolated and reset it between runs. Otherwise, one test's return can become the next test's mysterious preexisting condition.
Anthropic's agent-evaluation guidance emphasizes matching evaluation methods to the complexity of agent behavior. In this example, I would combine deterministic state checks with human review of explanations instead of asking one model to score everything.
The score that hides the failure
Our imaginary team already has an evaluation dashboard. It asks a second model to rate the helpfulness of each final answer from one to five. The wrong-order response scores highly because it is clear, polite, and offers a next step.
The dashboard is measuring something real: the quality of the explanation. It is simply not measuring the thing that failed.
I would keep that writing assessment and add a separate check against the test system's records. Which order was selected? Was the action permitted? Did one return exist at the end? Did the assistant ask for clarification when the customer had not identified the relevant purchase?
Now the response can be readable and unsuccessful at the same time. That is much more useful than an average score that blends the two into a reassuring number.
There is another subtle issue. A test might expect one exact sequence of tool calls, even though several valid routes reach the correct result. Overconstraining the path can punish a better agent. I would assert on required boundaries and final state, while allowing harmless variation in how the assistant gathers evidence.
For high-impact behavior, the reverse problem matters: a correct final state achieved through an unauthorized intermediate read is still unacceptable. That is why the suite needs both outcome checks and selected trajectory checks. The design should say which intermediate actions are forbidden, rather than treating the transcript as an opaque means to a successful end.
By the end of this review, the dashboard may look less impressive. It will be more informative. That is progress.
Use model graders where judgment is needed
A model grader can help assess whether an explanation is understandable or whether an answer addresses the request. Give it a narrow rubric and examples of acceptable and unacceptable responses.
Do not ask it to infer whether the refund really happened. Query the test ledger for that. Do not let a high writing score compensate for a forbidden action.
Calibrate the grader against human judgments on a sample. If the grader rewards long answers that dodge the question, fix the rubric before trusting its aggregate score. Keep the grader's version and configuration in the evaluation record.
Repeat runs without fooling yourself
Agent behavior can vary. Run important cases more than once, using a defined repetition policy, and report the distribution. “Passed once” and “reliably passes” are different statements.
When comparing two versions, use the same cases and starting conditions. Record prompt, model, tool, and retrieval configuration changes. A better average can still hide a regression in the one workflow that authorizes money movement.
A small suite will not establish a precise population-wide reliability rate. Treat it as a regression tool and a way to expose known failure classes, then expand it with representative, appropriately handled production cases.
Make the release decision explicit
For an early pilot, I would require all deterministic permission checks to pass, review every high-impact failure, and examine latency and cost alongside task completion. The exact thresholds belong to the workflow's risk and service expectations.
After launch, sample outcomes and feed failures back into the suite. Keep a holdout set so repeated tuning does not simply teach the system your test questions.
The useful question is not “Is this model smart enough?” It is “Can this version of our whole system complete these tasks, within these boundaries, often enough for this use?” That question gives a team something concrete to improve.
The Monday release, tried again
Before the next pilot, the team runs a small suite containing the wrong-order case and several neighboring cases. A second order with a different color. A canceled replacement. A missing address. A tool that returns an incomplete response.
The neighboring cases matter because fixing one prompt against one transcript can create a memorized success. The product needs to handle the underlying distinction, not just the exact wording of Monday's complaint.
A reviewer samples the explanations, while deterministic checks inspect records and permissions. Failures get grouped by cause: retrieval missed the replacement, the tool omitted order status, or the assistant acted before resolving ambiguity. Each category suggests a different fix.
The rollout can then be limited to a well-understood set of tasks with an escalation path. As the team gathers representative cases, it expands the suite and the product together. That is a more credible route to autonomy than announcing a universal success percentage from a handful of demonstrations.
A useful agent evaluation is a conversation between the product's promises and its observed behavior. What did we tell users this system could do? Under which conditions does it actually do that? Where should it stop?
If the release review can answer those questions, the green checks mean something. If it cannot, another polished demo will not close the gap.
Sources & further reading
Worked scenarios are illustrative. Technical references were checked on September 10, 2026.
Working through a similar problem?
Tell me what you are building and where it gets stuck.
Let’s talk ↗